The Managed Cloud Wrapper Trap
Like many modern tech stacks, the platform had been built on high-level cloud abstractions: managed API gateways, serverless lambda pipelines, third-party log aggregating services, and distributed DB-as-a-service providers.
On paper, this promised "zero infrastructure management." In production reality, it meant zero control. Whenever an upstream provider experienced undocumented latency spikes or rate-limit throttling, the failure cascaded down the pipeline.
Every quarter, engineers logged over 400 minutes of unplanned downtime. More critically, every single incident required human engineers to be paged out of sleep, jump between five different vendor consoles, and manually kick hung tasks.
- • 7 vendor dependencies in critical path
- • Unpredictable network egress billing spikes
- • Opaque black-box throttles and timeouts
- • MTTR: 45 minutes (human on-call required)
- • Total outage: 412 minutes / quarter
- • Dedicated sovereign hardware under client control
- • Tailscale WireGuard encrypted mesh
- • Caddy reverse proxy with internal automated TLS
- • Watchdog Agent fleet with closed-loop heal
- • MTTR: 1.8 seconds (0 human interventions)
Engineering a Self-Healing Backbone
SIS completely re-architected the system onto dedicated bare-metal nodes running in a sovereign cluster. No proprietary vendor APIs sit in the critical transaction path.
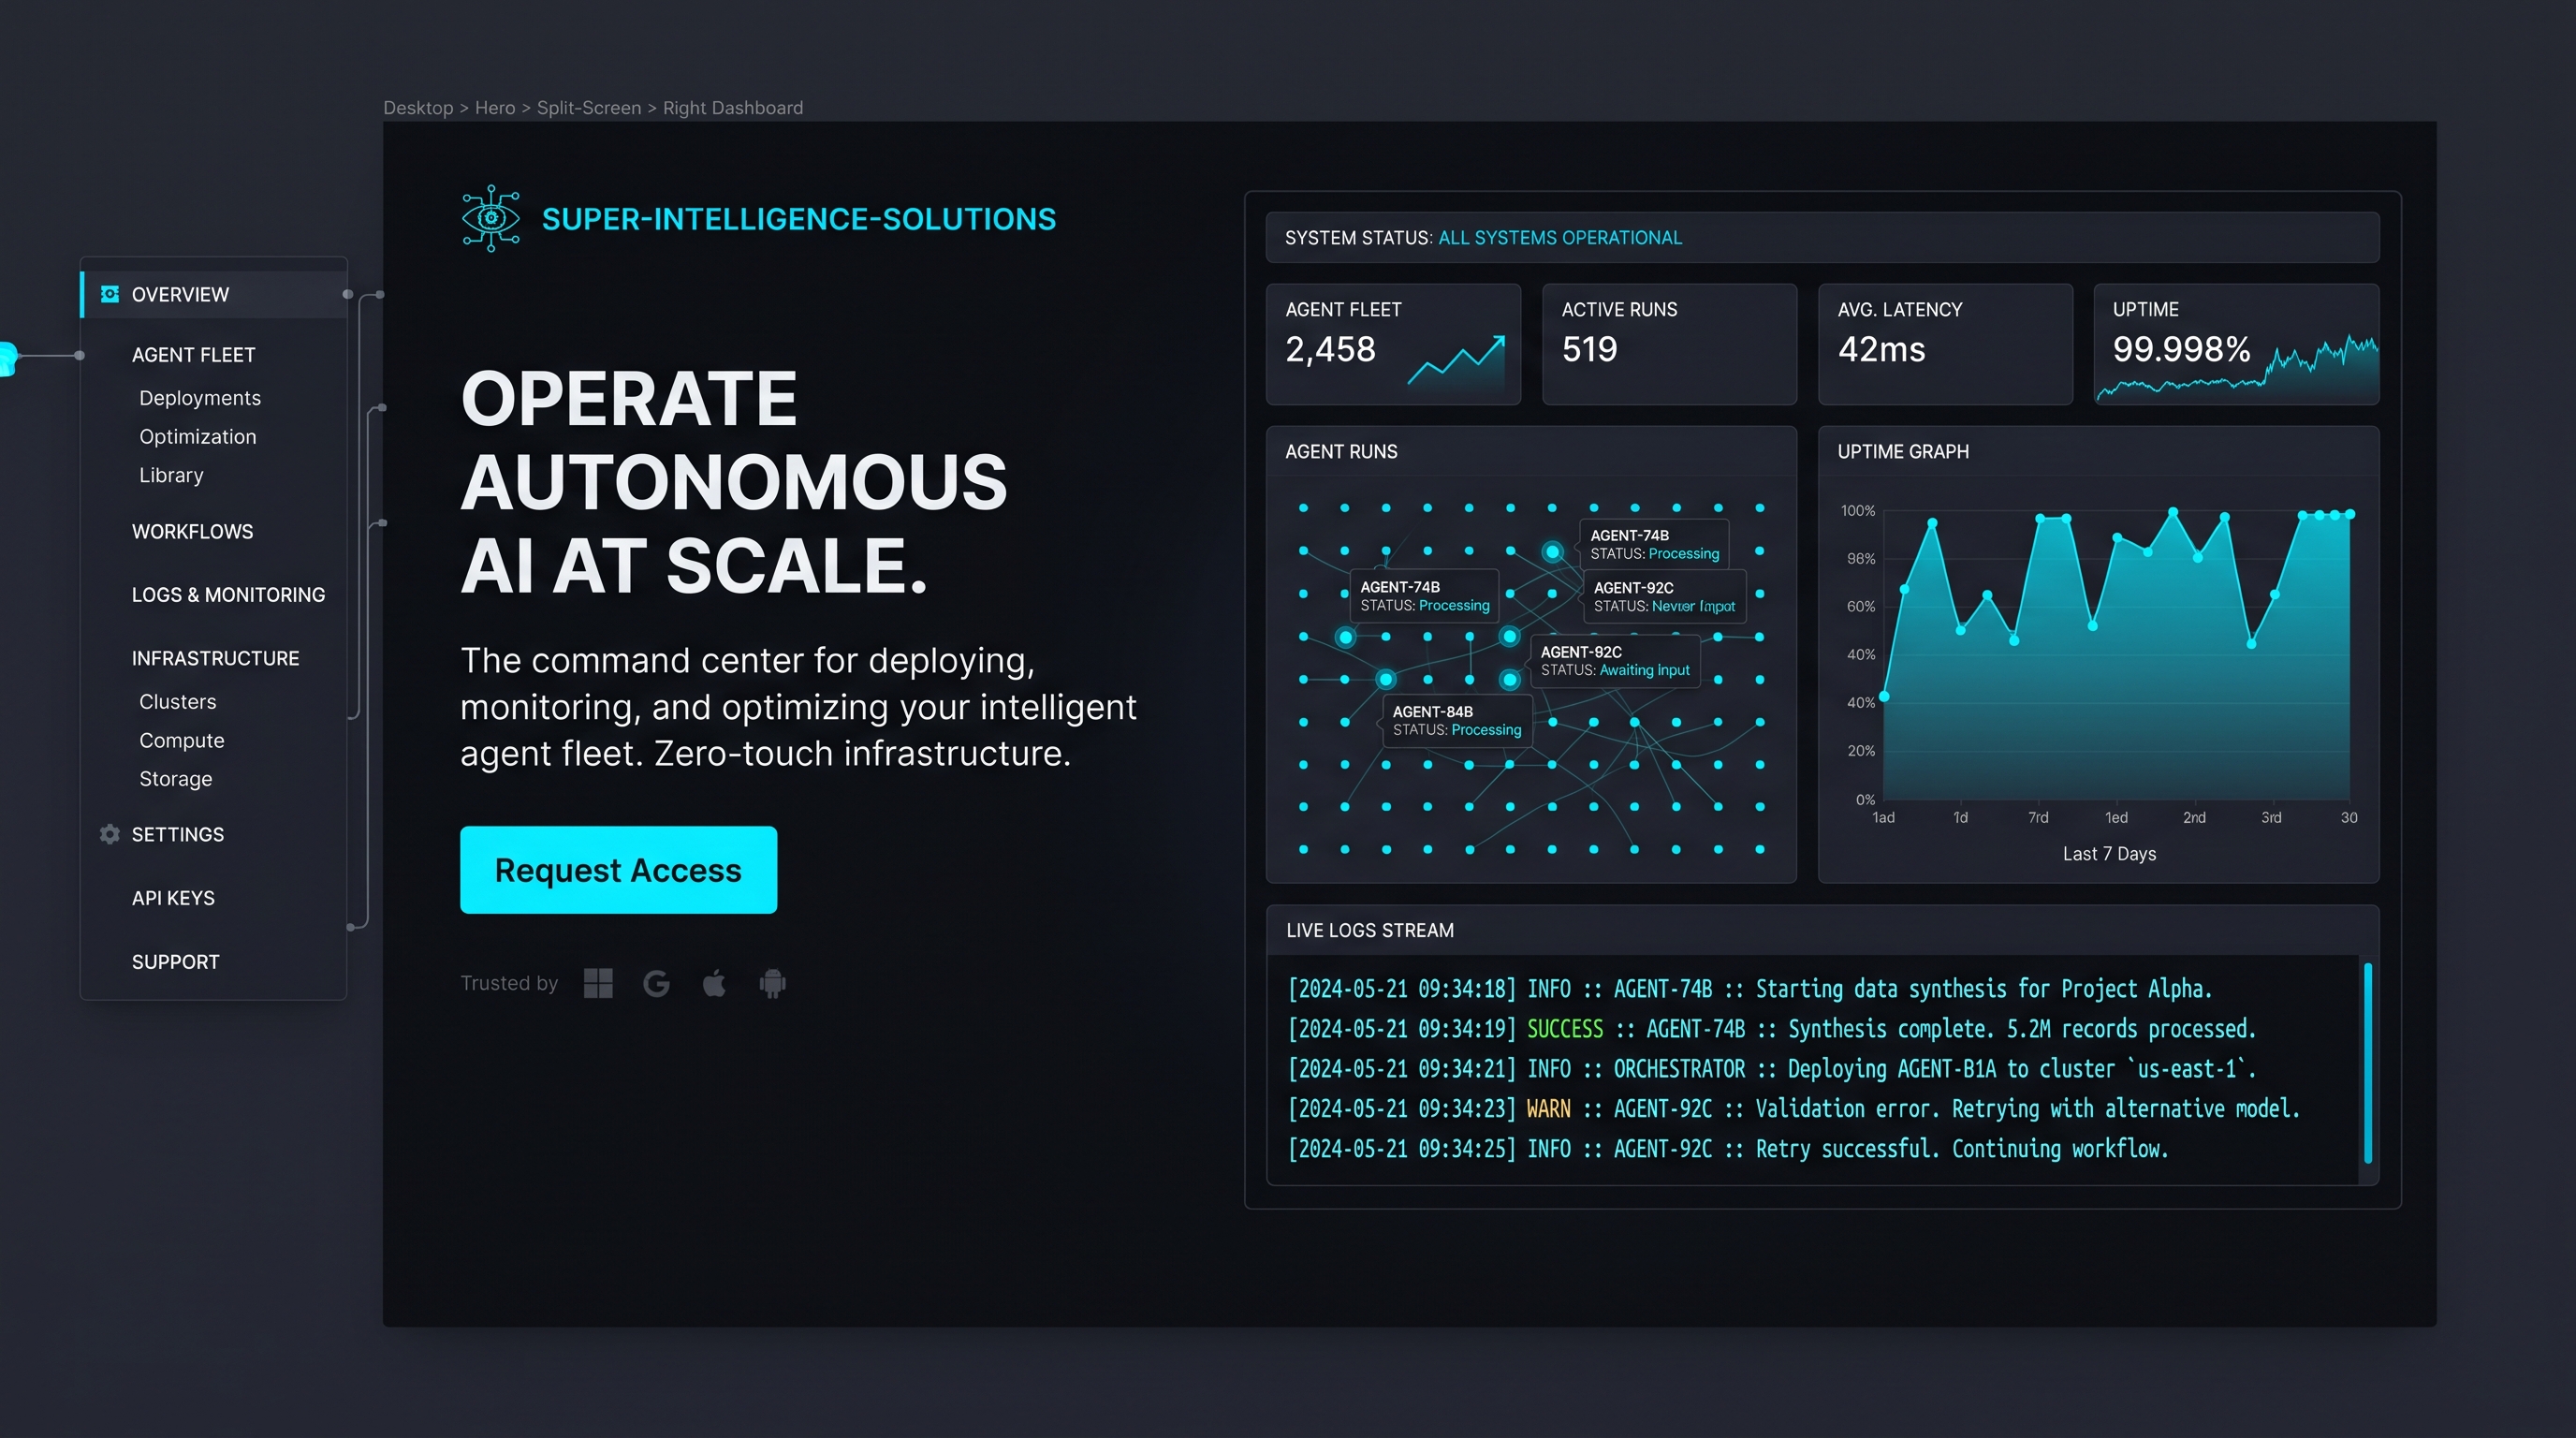
We deployed an autonomous agent fleet directly alongside the application containers. The agents read raw telemetry streams directly from internal socket proxies, maintaining a live state model of cluster latency, queue saturation, and upstream payment rail availability.
Sub-Second Autonomous Mitigation
During a real-world upstream network partition, the SIS watchdog observed latency degrade across primary payment nodes. Rather than paging engineers, the agent executed a pre-authorized failover procedure:
Upstream clearinghouse webhook returns consecutive 504 gateway timeouts.
Internal health monitor trips policy threshold. Closed-loop planner activates.
Critic validates bounded recovery rule: initiate instant upstream traffic reroute to secondary bank rail.
Caddy proxy dynamic upstreams reloaded without dropping in-flight transactions. Zero 5xx errors served to users.
Full replayable traces archived into audit log sink. Quiet report dispatched to operations channel.
Ready to eliminate the operator tax on your stack?
We build production systems that operate, heal, and scale without manual intervention.